A sitemap file lists the URLs of a website in a format readable by crawlers. Its role is to facilitate the discovery and indexing of pages by search engines like Google or Bing. Behind this seemingly simple function lie technical subtleties that determine whether this file will actually be utilized or simply ignored by crawlers.
XML Sitemap Tags: What Google Really Uses
Most guides present the XML sitemap as a file rich in metadata. In practice, Google only uses two of the four tags specified by the protocol. The <loc> tag, which contains the URL of each page, is the only mandatory one. The <lastmod> tag, which indicates the last modification date, is only taken into account if the dates are verifiably accurate and consistent over time.
The <priority> and <changefreq> tags, although present in many automatically generated sitemaps, are ignored by Google. John Mueller confirmed this publicly in 2026. Bing takes a similar stance, although its documentation is less categorical on the subject.
For a site that wants to take advantage of its sitemap, the rigor on <lastmod> matters more than the number of filled tags. An artificially updated modification date (without any real content change) can lead Google to reduce the crawling frequency of the site. You can observe how the sitemap page of Un Joli Rêve structures its URLs with consistent dates, a choice that reflects this reliability logic.
XML Sitemap and HTML Sitemap: Two Files, Two Audiences
The XML sitemap is aimed at crawlers. It is a technical file, accessible at a URL like /sitemap.xml, that lists the pages along with their metadata. The HTML sitemap, on the other hand, is a page of the site intended for human visitors. It presents the structure in the form of clickable links, organized by category or theme.
The XML sitemap remains the priority for natural SEO. The HTML sitemap can improve internal navigation, but it does not replace the XML file in the eyes of search engines. On a small site (a few dozen pages), the HTML sitemap adds little value if navigation is already clear.
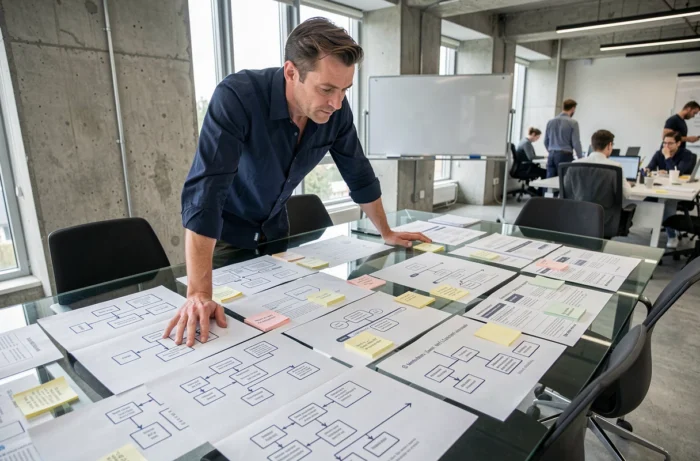
For large sites, combining both formats makes sense. The XML file ensures that crawlers discover all URLs, including those buried deep in a structure. The HTML sitemap, in turn, helps visitors find content without going through the internal search engine.
Sitemap Directive in robots.txt: A Convention, Not a Standard
Many webmasters add a line Sitemap: https://example.com/sitemap.xml in their robots.txt file. This practice is widespread, but it is not part of the official robots.txt standard (RFC 9309). It is a convention adopted by search engines without normative value.
Google recognizes and processes this directive. However, nothing obliges a search engine to comply with it. For sites that want to increase their chances of indexing, directly submitting the sitemap via Google Search Console or Bing Webmaster Tools remains the most reliable method.
Three ways to signal a sitemap to search engines coexist:
- Manual submission in Search Console or Bing Webmaster Tools, allowing for tracking of errors and indexing status
- The
Sitemap:directive in the robots.txt file, practical but without normative guarantee - Automatic discovery by crawlers, which follow the internal links of the site to find the sitemap file (the least controllable method)
When a Sitemap Actually Changes a Site’s Indexing
A sitemap does not automatically speed up indexing. It also does not guarantee that a page will be indexed. Its real usefulness depends on the structure and size of the site.
A site with a few pages and a coherent internal linking structure does not need a sitemap for Google to discover all its content. Crawlers follow internal links and naturally find accessible pages. The sitemap becomes relevant in specific cases:
- Large sites, where some pages are several levels deep from the homepage
- Sites with orphaned content (pages not linked by internal links)
- Recently created sites, which do not yet have incoming links for crawlers to discover them
- News or e-commerce sites, where content changes frequently and a reliable
<lastmod>date helps prioritize crawling
On the other hand, including in a sitemap URLs blocked by the robots.txt file or returning a 404 error sends contradictory signals to crawlers. A clean sitemap, listing only indexable and up-to-date pages, will always be more effective than a comprehensive file filled with outdated URLs.
Update of Google Documentation in 2026
As of March 1, 2026, Google has removed from its official documentation the instructions explaining how to submit a sitemap for sites created with Google Sites. This removal, noted in updates from Google Search Central, suggests that the automatic management of sitemaps by certain platforms makes manual submission unnecessary in these contexts.
This removal does not undermine the usefulness of the sitemap for self-hosted sites or those built on CMSs like WordPress. It confirms a trend: Google is continuously improving its ability to discover pages without manual intervention, while maintaining the XML sitemap as a complementary tool for complex sites.
The sitemap remains a simple technical file whose effectiveness relies on two principles: listing only valid URLs and maintaining reliable modification dates. For well-structured sites with good internal linking, it acts as a safety net rather than an indexing lever. For complex architectures or large catalogs, it remains a direct communication tool with search engines, provided it is kept up to date.